 US
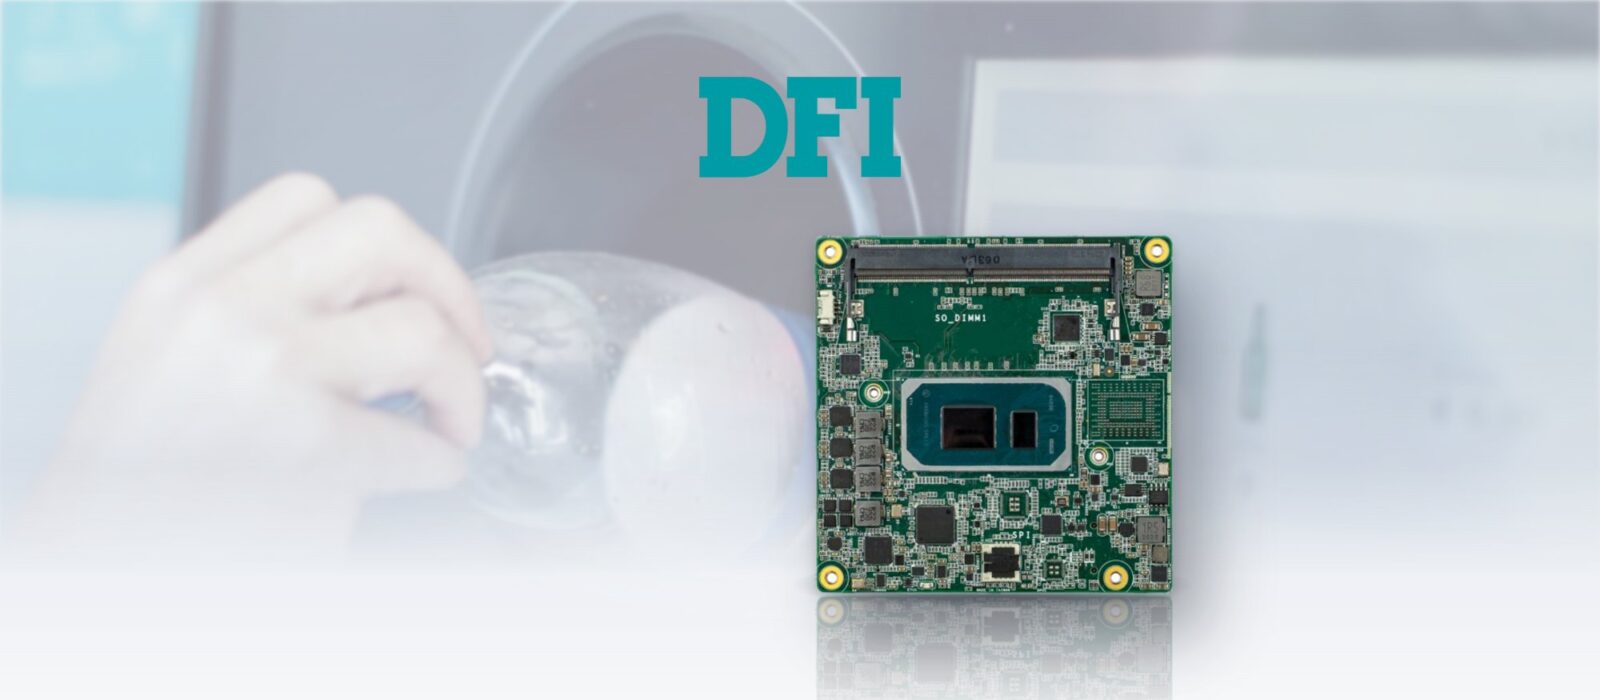
COM Express SBC Utilizes Intel Iris Xe Graphics for Deep Learning AI
Reverse vending machines (RVMs) reward people for recycling: insert a plastic bottle, glass bottle or can, and the machine scans, sorts and stores it, then pays out cash or a voucher. As deposit return schemes spread, machines have to recognize containers faster and more reliably, and that is increasingly a job for AI.
An RVM manufacturer integrated DFI’s TGU968 COM Express module into its latest machine, using the 11th Gen Intel Core processor and its integrated Iris Xe graphics to run deep learning recognition. It is the kind of system we supply for retail and self-service.
Inside a reverse vending machine
Every container goes through the same sequence in seconds, and the AI step decides how fast the queue moves.
-
Insert
Container inThe user feeds in a bottle or can, and the machine moves it past its cameras and scanners.
-
Recognize
Deep learningMachine vision and AI identify the container by its shape, material and label, checking it is eligible for a refund.
-
Sort
Crush and storeApproved containers are crushed or kept whole and sent to the right storage bin.
-
Reward
RefundThe machine issues cash, a voucher or a digital reward.
Why a COM Express module
- 01Module plus carrier
- The module carries the processor and memory and plugs into a carrier board built for the machine’s I/O.
- 02Upgradeable
- A newer module of the same type can replace the old one, so the machine’s compute can improve without redesigning its electronics.
- 03Simpler architecture
- One standard compute block across the product range simplifies design and long-term support.
- 04Compact form factor
- A Compact module keeps the electronics small inside a machine full of mechanics, cameras and sensors; see our COM Express module types FAQ.
Our system-on-module explainer covers how the module and carrier split works, and our COM-HPC vs COM Express comparison shows when the newer standard is worth the move. We also supply COM Express carrier boards.
The DFI TGU968
An 11th Gen Intel Core COM Express Compact module with Iris Xe graphics and 2.5GbE.
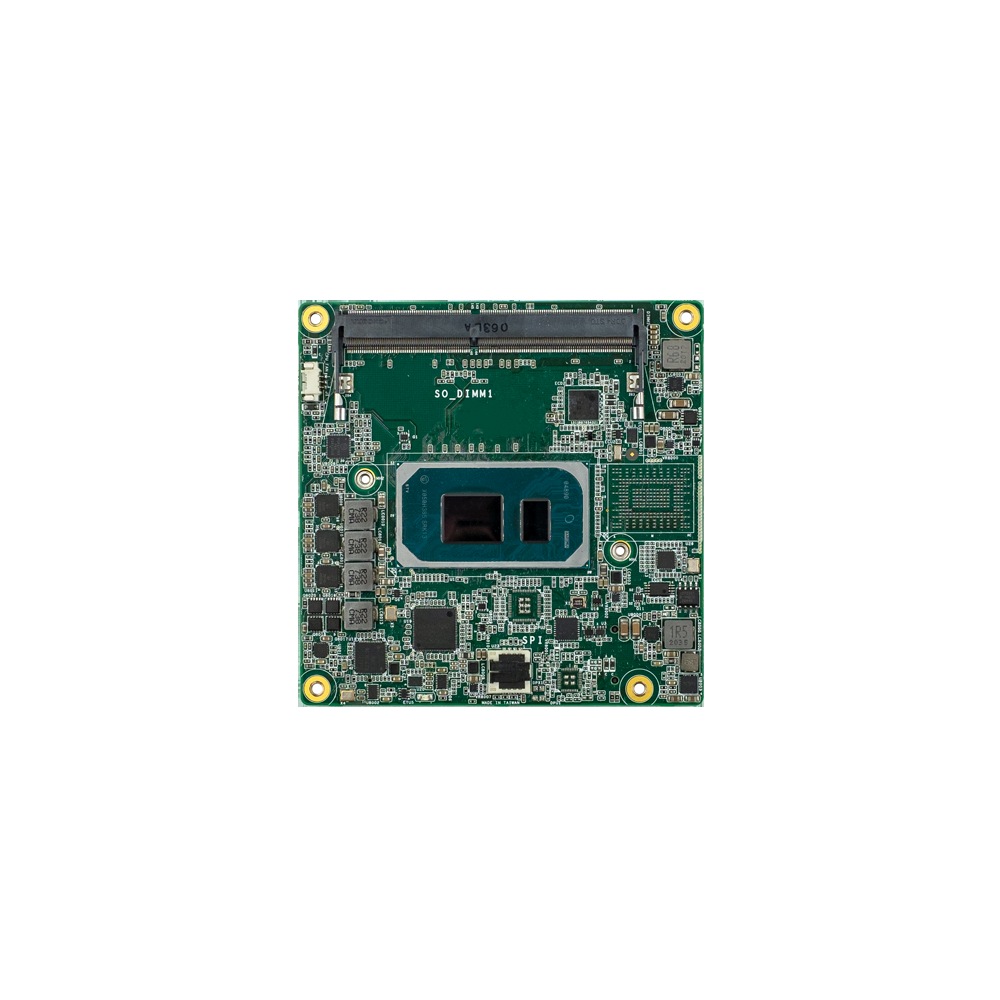
TGU968
11th Gen Intel COM Express Compact Module with 2.5GbE
- Processor
- Intel Core 11th Gen (Tiger Lake)
- Networking
- 1× 2.5GbE
- Memory
- 2× DDR4-3200 SO-DIMM, up to 64 GB
Deep learning on integrated graphics
- 01Iris Xe on the processor
- The Tiger Lake Core i5 and i7 processors include Iris Xe graphics on the same chip, sharing system memory instead of needing a separate GPU.
- 02Lower size, power and cost
- No discrete graphics card means a smaller, cooler and cheaper system, removing a traditional barrier to AI in machines.
- 03Optimized with OpenVINO
- OpenVINO optimizes trained models to run efficiently on the CPU and Iris Xe graphics together.
- 04Built for inference
- Iris Xe handles inference, running trained models on new images; training stays on more powerful hardware.
For heavier workloads, such as many camera streams or training large models, a discrete GPU or a dedicated AI platform is the better fit; our iGPU vs dGPU FAQ sets out the trade-offs, and our inference vs training FAQ explains the difference between the two workloads.
Intel Xe graphics combined with the OpenVINO inference engine reach performance levels previously only seen on much more expensive AI platforms. It opens AI up to a wider audience, giving software developers and ML professionals the tools to build applications that make a difference.
What the module delivered
Integrated graphics and OpenVINO brought deep learning into the machine without adding a GPU.
-
Outcome 01
Up to five times faster
Recycling speed increased up to five times compared with traditional single-feed machines.
-
Outcome 02
Less waiting, more recycling
Faster recognition cuts the time each return takes, improving the effectiveness of the process.
-
Outcome 03
AI without a discrete GPU
Iris Xe and OpenVINO kept size, power and cost down.
-
Outcome 04
Ready to upgrade
The COM Express design lets future modules drop in as the technology improves.
COM Express and edge AI FAQs
-
What Are the COM Express Module Types?
COM Express is a PICMG standard for computer-on-modules, and its pin-out types define which interfaces a module provides. Type 6 is the most common, with display outputs, USB and PCIe for general embedded systems. Type 7 is headless, with multiple 10GbE ports for server-class edge use. Type 10 is a smaller, lower-power pin-out for Mini modules.
-
What Is OpenVINO?
OpenVINO is Intel's open-source toolkit for optimizing and running AI inference. It takes models trained in frameworks such as PyTorch, TensorFlow or ONNX, optimizes them, and runs them efficiently on Intel hardware, including CPUs, integrated GPUs such as Iris Xe and Arc, and the NPUs in Core Ultra processors.
-
iGPU vs dGPU: What Is the Difference?
An iGPU (integrated GPU) is built into the processor and shares the system memory, so it adds no extra power, heat or cost. A dGPU (discrete GPU) is a separate graphics processor with its own memory, offering far more performance but needing more power, cooling and space. For edge AI, iGPUs suit lighter inference; dGPUs suit heavy workloads.
-
What Is a Reverse Vending Machine?
A reverse vending machine (RVM) takes back empty drinks containers, such as plastic bottles, cans and glass, and gives the user a refund or reward. It identifies each container by its barcode and shape, checks it is eligible, then crushes, sorts and stores it. RVMs are the collection point for deposit return schemes.
-
AI Inference vs Training: What Is the Difference?
Training is how an AI model learns: it is fed large sets of labeled data and adjusted until it predicts accurately, which needs powerful GPUs. Inference is using the trained model on new data to make a decision, which is lighter per image and usually runs in real time on an edge computer beside the camera or machine.
Adding AI to a machine you build?
Tell us about your application and a member of our team will get right back to you.