 US
Data Centre GPUs
Data Centre GPUs for AI Inference and Training
A data centre GPU is a passive accelerator built for servers, relying on the chassis fans for cooling so several cards can run side by side under constant load. The range covers HBM accelerators for large models, Ada Lovelace cards for inference and graphics, and Blackwell Server Edition cards for mixed AI and visual work.
Options include memory from 24 GB to 141 GB, NVLink bridges on the largest cards, Multi-Instance GPU partitioning and power from 72 W slot-powered cards to 600 W, suited to edge AI servers, video analytics, simulation and private AI deployments.
Speak to a data centre GPU specialist to match memory, power and airflow to your server.


Browse Our AI GPUs
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: L40
- AI Performance: 724
- Display Outputs: 4x Display Ports
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: NVIDIA L40S
- AI Performance: 1,466 TOPS
- Display Outputs: 4x Display Ports
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: H100 NVL
- AI Performance: 3,341 TOPS
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: H100 PCIe
- AI Performance: 3026
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: RTX PRO 4500 Blackwell Server
- AI Performance: 1600
- Temp: 10°C to 45°C [50°F to 113°F]
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: NVIDIA H200 NVL
- AI Performance: 3,341 TOPS
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: NVIDIA RTX PRO 6000 Blackwell Server
- AI Performance: 4,000 TOPS
- Display Outputs: 4x Display Ports
- Temp: 10°C to 45°C [50°F to 113°F]
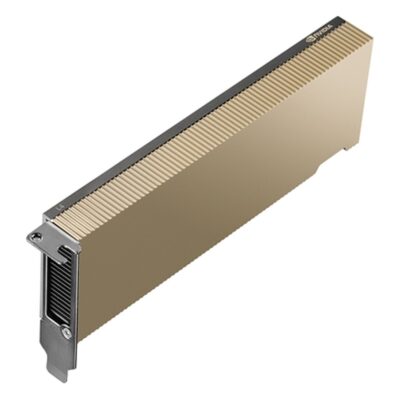
- GPU / AI Accelerator: Discrete GPU (PCIe)
- GPU: NVIDIA L4
- AI Performance: 485 TOPS
Data Centre GPU Ranges Configured by Things Embedded
We work with the leading manufacturers of server GPUs, so the ranges below are the ones we specify for edge AI servers and rack systems. Compare them by memory, power and interconnect, then browse the cards above or ask a data centre GPU specialist.
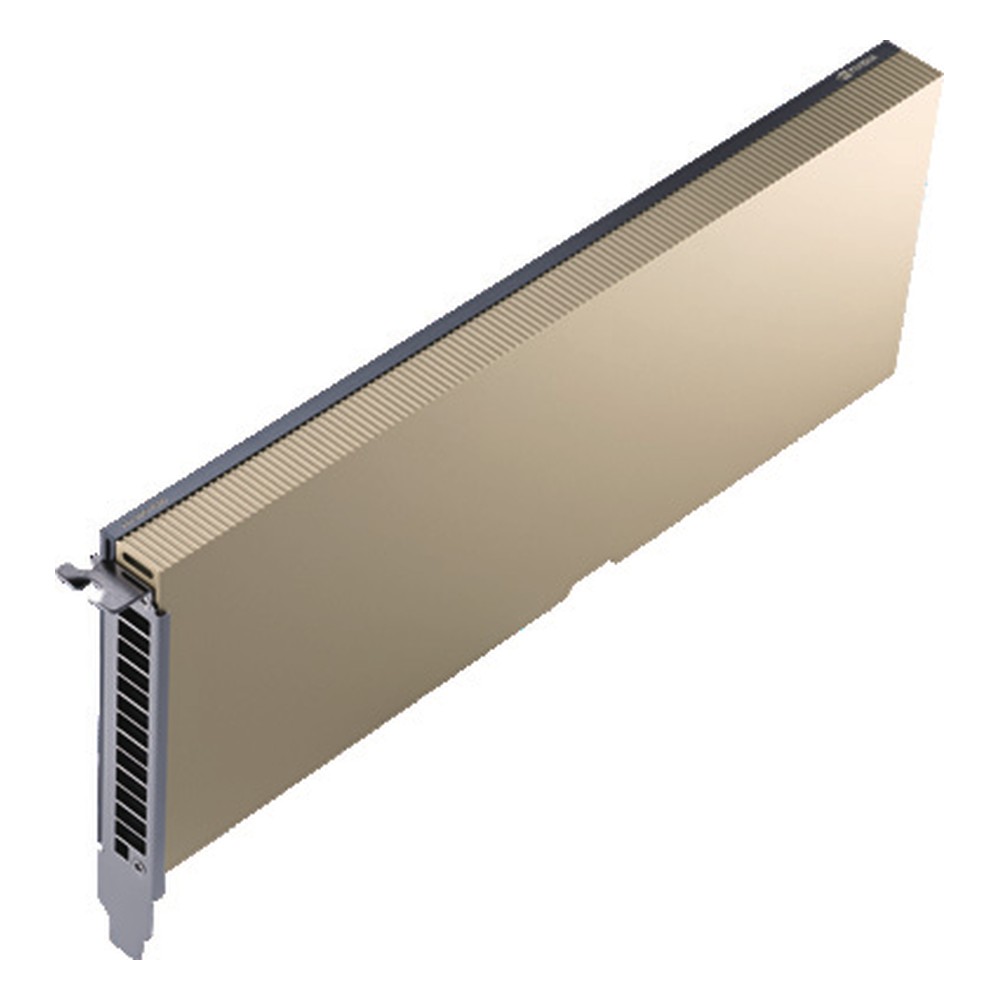
RTX PRO Blackwell Server Edition
Passive Blackwell cards with GDDR7 ECC memory and PCIe 5.0, from the single-slot 32 GB RTX PRO 4500 to the 96 GB RTX PRO 6000.
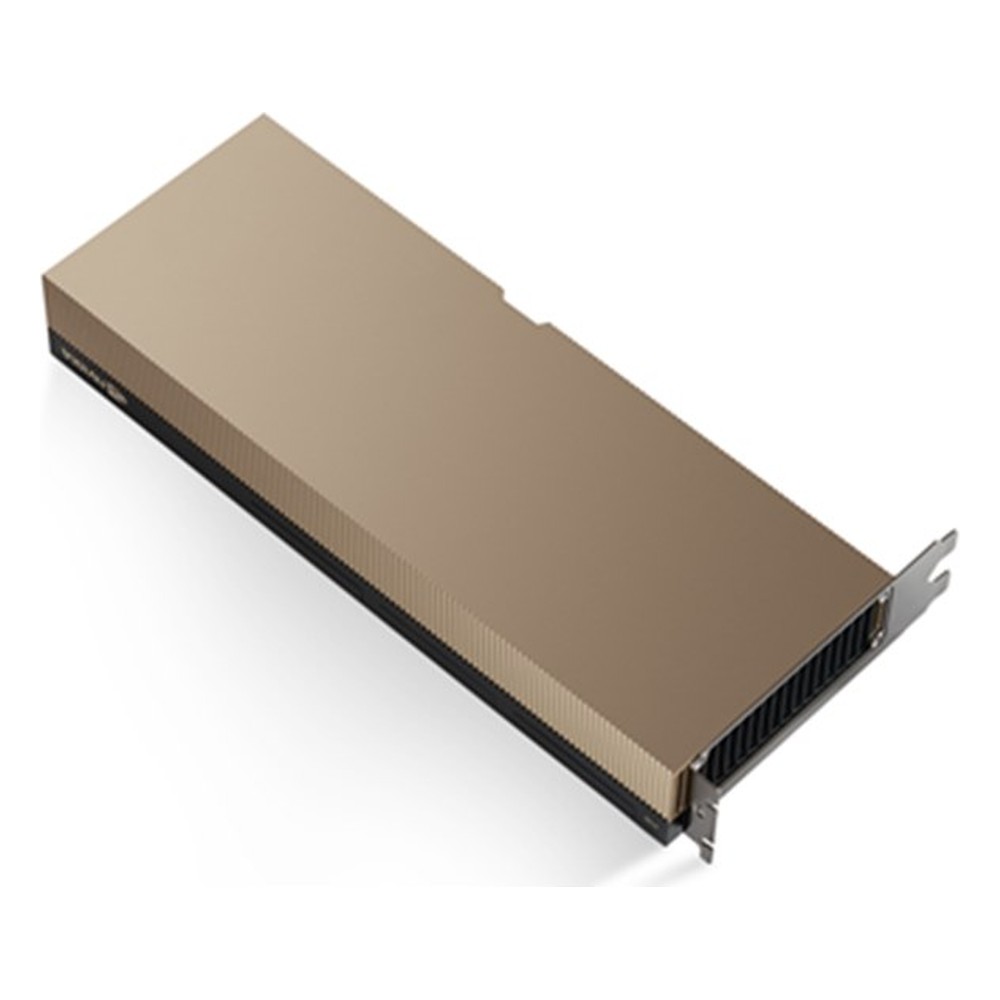
Hopper HBM Accelerators
H100 and H200 NVL cards with up to 141 GB of HBM3e and NVLink bridges for large models and HPC.
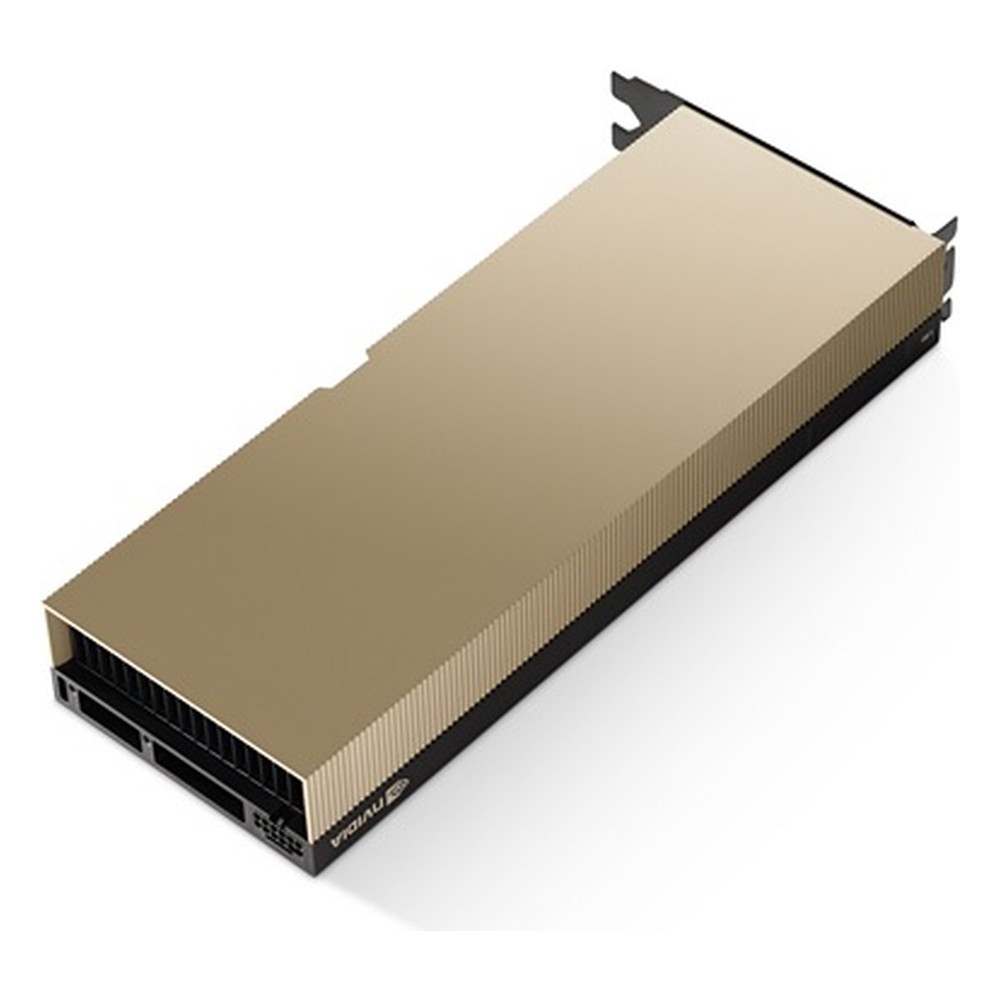
Ada Lovelace L-Series
The low-profile 72 W L4 for dense inference, and the 48 GB L40 and L40S for AI with graphics.
Not sure which range fits? Tell us the application and we will recommend the right model.
What to Specify in a Data Centre Accelerator
Our GPU specialists specify every accelerator against the server, its airflow and power supplies and the models you will run. These are the choices we work through with you before recommending a card.

Memory and Bandwidth
HBM cards hold the largest models in memory; GDDR cards suit inference and graphics at lower cost per card.
Server Airflow
Passive cards depend on server fans moving air front to back, so the chassis must be qualified for the card.
Power per Card
From 72 W slot-powered cards to 600 W cards on a 16-pin connector; the power supplies set how many you can fit.
Multi-GPU Scaling
NVLink bridges join two or four of the largest cards; Multi-Instance GPU splits one card between users.
Slot and Height
Low-profile single-slot, full-height single-slot and full-height dual-slot cards suit different server sizes.
Operating Range
Server GPUs expect a conditioned inlet; edge sites need a server rated for the room the card will live in.
Data Centre GPU Innovation & AI Server Insights


Speak to a Data Centre GPU Specialist.
Tell us the models you will run, the server and the power and airflow it provides. We will recommend the right accelerators, then fit, configure and burn-in test them in the server before it ships.